Is Spider-Man an accident?
Testing the Marvel network against three kinds of "nothing special going on here," then growing a network that tries to build its own Marvel.
Testing the Marvel network against three kinds of "nothing special going on here," then growing a network that tries to build its own Marvel.
Week 1 found a heavily skewed network: 303 characters, mean in-degree 5.89, and one hub — Spider-Man, cited by 106 others, almost double the runner-up (Hulk, 64). Is a hub that size just what falls out of scattering 1,784 links across 303 nodes — or does it take something more deliberate, an actual rich-get-richer mechanism?
No new data this week: everything below runs on the same 303 nodes and 1,784 directed edges
from data/week1, computed live in your browser, across four questions. Could pure
chance produce this? What survives once every character's link count is frozen and only
who connects to whom is randomized? Can a growth model that favors the well-connected
reproduce it — and where does it break? And what does this shape mean for an individual hero's
own connections?
Could Spider-Man's 106 in-links just be chance? The simplest null model says every possible directed pair of characters is equally, independently likely to link: an Erdős–Rényi (ER) random graph with the same 303 nodes and 1,784 edges as the real network. If scattering that many edges at random can produce a hub that size, an ER draw should occasionally come close.
It doesn't. Across 300 offline ER draws, the biggest hub's in-degree ranged from 11 to 18 (mean 13.9, standard deviation 1.2) — Spider-Man's 106 is about 6× larger than the largest draw, and roughly 74 standard deviations above the mean. Draw your own random network below and see where its biggest hub lands.
Each draw independently places 1,784 directed edges among 303 nodes at random (no self-loops, no repeats) and plots the resulting in-degree CCDF against the real network's.
ER throws away how many links each character has, too — a strong null, maybe too strong. The tighter question: keep everyone's exact in- and out-degree fixed, scramble only who links to whom. Does the network still look distinctive?
The shuffle keeps every character's degree the same but changes who connects to whom: repeatedly take a chain a→b, b→c, c→d and rewire it to a→c, c→b, b→d. Two statistics, defined precisely:
Offline, across 300 shuffles (3,000 swaps each): clustering's null mean was 0.180 (sd 0.009) — the real value sits about 14 standard deviations above it, beyond all 300 shuffles (empirical p ≈ 0). Reciprocity's null mean was 0.069 (sd 0.007) — the real value sits about 44 standard deviations above that, again beyond every shuffle. Degree alone doesn't explain this network's triangle-heavy structure or its mutual-citation rate.
The chart below starts pre-populated with shuffles, so the null distribution is visible immediately — pick a statistic, or run more yourself.
How unusual is the real network?
StatisticEach shuffle is a fresh copy of the real network, swapped from scratch (not a running chain), matching the offline method above but with fewer swaps per realization for responsiveness. 40 run automatically on load; use the button for more.
One more thing we checked offline but didn't add as a control: does the 9-character island Week 1 found ever reconnect to the giant component under this shuffle? Across all 300 realizations, the giant component stayed exactly 277 nodes, every time (standard deviation 0) — not by chance, but by construction: a swap only ever rewires edges along an existing directed walk (a→b→c→d), which can never cross between two components with no edges between them. This null can't even ask whether the island would reconnect — the component split is invariant by construction, not by result. That's why it isn't offered as a third toggle above: a histogram with zero variance wouldn't be testing anything.
Preferential attachment: grow to 303 nodes one at a time, and give each newcomer m outgoing links to existing characters — chosen with probability proportional to how many in-links they already have. It's the classic rich-get-richer mechanism, in its directed citation-network form (the Price model), which fits our directed network better than the usual undirected Barabási–Albert setup. Out-degree is exactly m for every non-seed node by construction (the growth ingredient); in-degree accumulates by preference (the rich-get-richer ingredient).
This is a generative hypothesis tested against the data — not a claim about how the Wikipedia article network actually got written.
At m=6 (6×303 ≈ 1,818 edges, close to the real 1,784), 50 offline trials all produced a bigger hub than Spider-Man: max in-degree 116–166 (mean 141) against the real 106 — preferential attachment doesn't just reproduce a big hub here, it overshoots. Lowering m brings the hub down (m=3: 70–137, mean 99, much closer; m=2: 44–125, mean 79) but pulls the edge count further from 1,784 — no single m matches both density and hub size. And at every m, every trial: one connected component, zero isolates — versus the real network's 17 isolates and a 9-character island. A model where everyone who joins immediately attaches can't produce someone nobody ever mentions.
Move the slider and regenerate to see for yourself.
Grows a fresh directed preferential-attachment network to n=303 nodes with the chosen m, then plots its in-degree CCDF against the real network's.
Preferential attachment depends on history: characters arrive one at a time, and each newcomer is more likely to connect to whoever's already popular, so an early lead can snowball into a hub like Spider-Man. But what if the Marvel universe was born all at once?
If all 303 characters existed simultaneously, there'd be no established popularity for a newcomer to follow — everyone would start with the same shot at new connections. That's the counterfactual below: a second model, same 303 characters and roughly the same edge budget, that links nodes uniformly at random instead of preferring the well-connected. It's not a claim about how Marvel's Wikipedia network actually came to exist — it's a way of asking how much of the hub structure could come from history alone.
Sequential growth adds one character at a time, wiring each newcomer's m links proportional to how connected existing characters already are (the same rule as above). Big Bang creates all 303 at once and wires the same m links per character uniformly at random — no regard for who's already connected. Switch models or click "New universe" for a fresh run; node size shows degree, and the largest hub is highlighted in gold. Hover a node (mouse only) for its name and degree.
Hover a node to see who occupies it and how connected it is in this run.
Run each model a few times at the same m. Big Bang spreads connections fairly evenly — most nodes end up a similar, modest size, and the largest hub barely varies run to run. Sequential growth, at that same m, reliably produces one or two stand-out characters, because whoever gets ahead early keeps attracting a disproportionate share of new links. That's the mechanism in miniature: Spider-Man's 106 real in-links aren't just abstract "popularity" — in a growing network, being popular early is itself an advantage that compounds. In a universe born all at once, there's no "early" for that advantage to attach to.
None of this shows preferential attachment is what actually produced the real Wikipedia network — the CCDF comparison above already found PA, at the edge-matched m, reliably overshoots Spider-Man's real in-degree. What it does show is why network history can matter: a heavy-tailed degree distribution is consistent with a growth-plus-preference story, but consistent isn't proof — this counterfactual just isolates what history specifically contributes.
Definitions: on the undirected projection (same one used for clustering above), a character's degree is their number of distinct neighbors, and their average neighbor degree is the mean degree of those neighbors. Network-wide, ⟨k⟩ = 9.465, while the edge-weighted mean neighbor degree ⟨k²⟩⁄⟨k⟩ = 22.08 — more than double. That gap is the friendship paradox. It's worth stating plainly that ⟨k²⟩⁄⟨k⟩ is a pure function of the degree sequence, so it's mathematically guaranteed to survive a degree-preserving shuffle — not something this page needs to test.
What isn't guaranteed is what it looks like character by character. Of the 286 connected characters, 250 (87.4%) have neighbors who are on average more connected than they are; the other 36 (12.6%) out-rank their average neighbor. Only two are never out-popularitied by any neighbor at all: Spider-Man, and, inside the isolated Morituri island, Radian.
Search for a hero below to see their own numbers.
Each dot is one connected character (own degree vs. average neighbor degree, log-log). The dashed diagonal marks equality: above it, your neighbors out-rank you on average; below it, you out-rank them. Click a dot or search a name.
No hero selected yet — click a dot or find one above.
We plotted the in-degree CCDF P(K ≥ k) on the frozen Week 1 snapshot (303
characters, 1,784 directed links) against two nulls: an ER random graph,
whose in-degree is exactly Poisson with
λ = 1,784/303 ≈ 5.89, and a 200-seed
ensemble of Barabási–Albert graphs (N = 303, m = 3 — mean
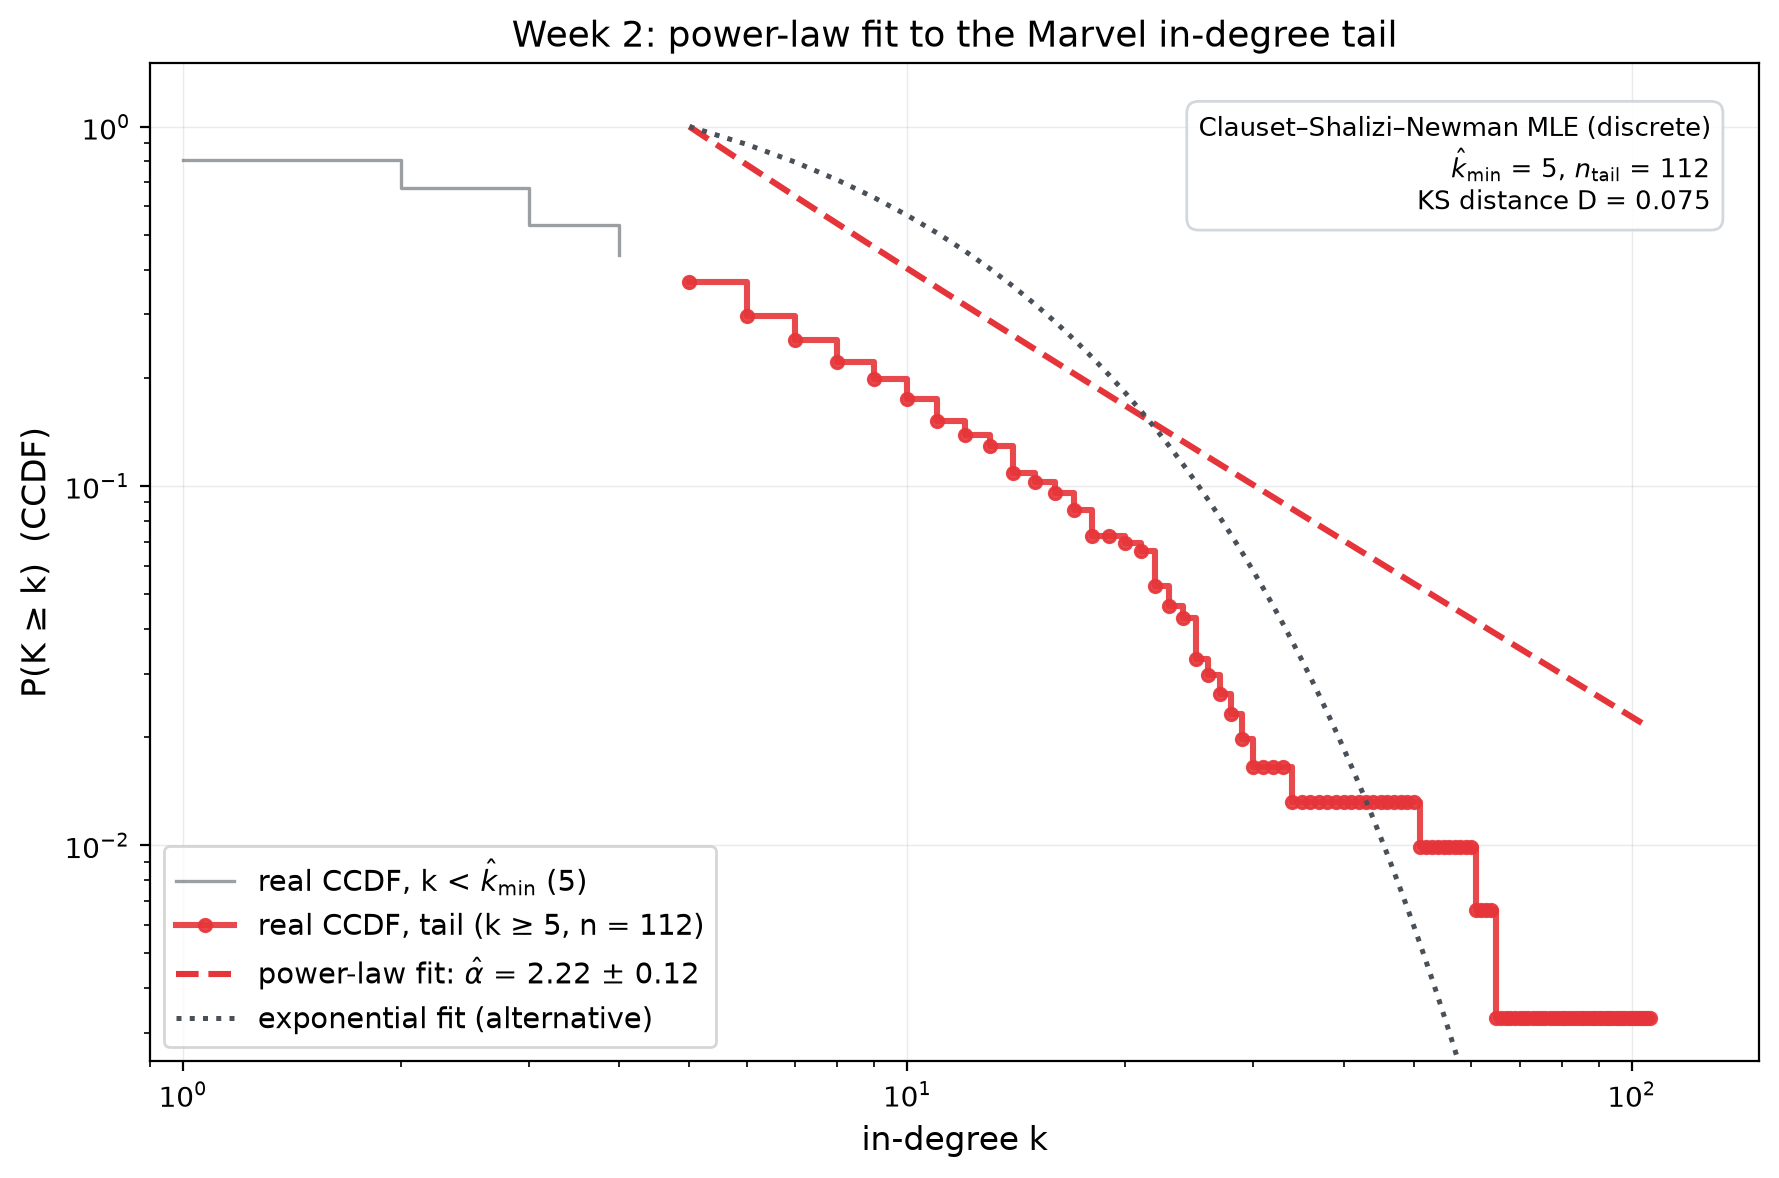
degree 5.94, matching ours), shown with a 5–95% band. A discrete power-law fit
(Clauset–Shalizi–Newman MLE, via the powerlaw package) then summarizes the tail:
exponent α̂ with its standard error, and a self-selected cutoff k̂min.
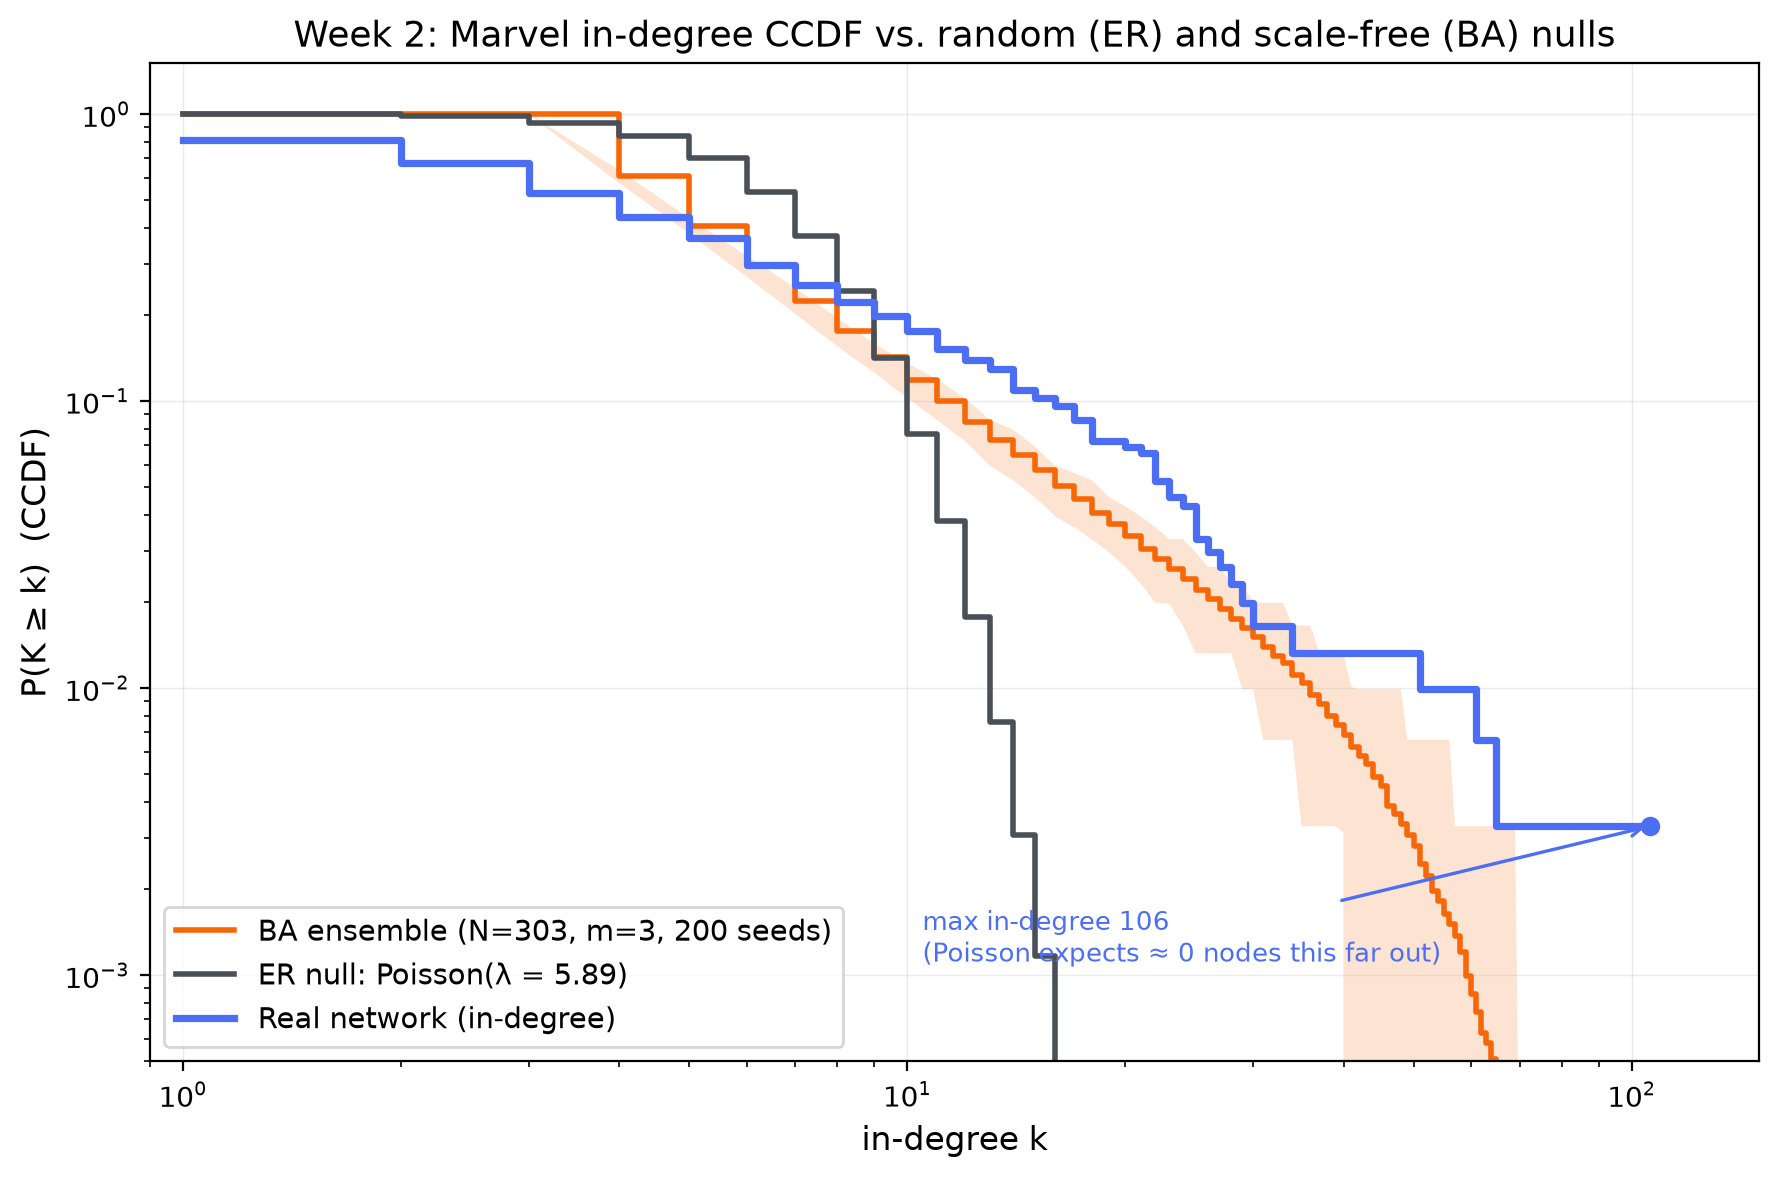
Not random. Under ER, a character with in-degree 20 or more should essentially never exist — expected count 0.0012, real count 21. A degree of 106 is 1 × 10−91 off the Poisson scale: the gray curve exits the chart by k ≈ 18, while the real network still has 22 characters beyond it.
Heavier than BA. From k ≈ 7 on, the real CCDF runs above the BA ensemble's 95% band and stays there; the fitted exponent (α̂ = 2.22) sits well below BA's theoretical 3.0 (smaller exponent = heavier tail), and Spider-Man's 106 clears BA's ensemble max of 77. Forced to choose between random and BA: BA, easily — it just understates Marvel's skew.
Neither, strictly. The power law describes the tail, not the whole network: only 112 of the 245 cited characters sit in the fitted region, and a network this small carries wide uncertainty on α̂. "Scale-free-looking tail" is as far as this data goes.
What we can't conclude (for this question):
Pulling the four sections together:
So: no, Spider-Man isn't an accident of scale or density. Something like rich-get-richer growth fits the real hub structure far better than any random baseline — but that's a hypothesis this data is consistent with, not something these four tests prove happened, and even its best-fitting version can't explain the 17 characters nobody bothered to link to.
analysis/build_week2.py,
run against the same frozen data/week1/ that Week 1 uses, writing
data/week2/week2_summary.json. Every interactive figure recomputes its own live
version of the same algorithm in your browser — nothing here is hand-typed separately from
the code that produced it.